
 Submit a find



 한국어
 日本語
 Español
 Français
 Deutsch
 简体中文
 繁體中文
 Português
 Bahasa Indonesia
 ไทย
 Italiano
 Tiếng Việt
 Türkçe
 Polski
 Русский
 Back to the lab
 JEVLAB NEWS Research & data
SpaceXAI Releases Grok 4.7
AI-assisted summaries and translations. Check original sources for context and performance claims.
SpaceXAI has launched Grok 4.7, featuring a larger base model and enhanced reinforcement learning for complex tasks. While the model shows significant gains in coding and document analysis, its overall intelligence score improvement remains modest compared to top-tier competitors.
Translated summary · AI-assisted; check the original.
 Translated summary · AI-assisted; check the original.

The complete thread, at a glance
Independent AI-assisted summaries of CHOI’s connected posts. Images and videos belong to their original creators. Source claims have not been independently verified.
Grok 4.7 Announcement
SpaceXAI has officially released Grok 4.7, now available across Cursor, Grok Build, and the Grok API.
Model Enhancements
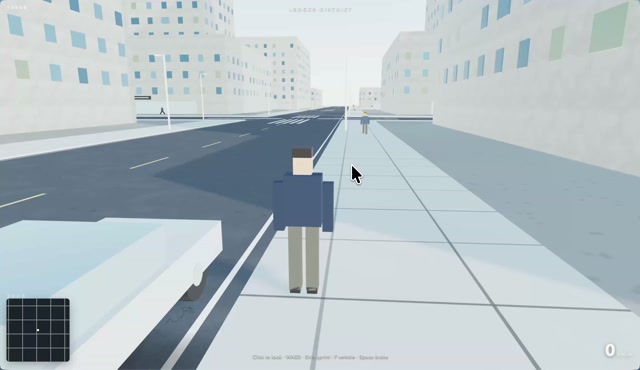
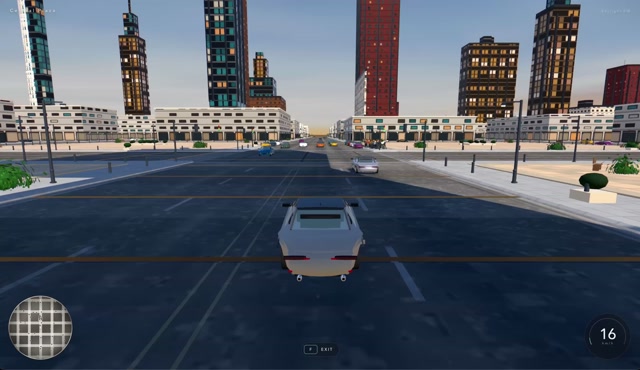
Grok 4.7 introduces a larger base model and focuses reinforcement learning on long-duration tasks. The company reports improved detail in generative tasks, such as the urban game demo.
Benchmark Performance
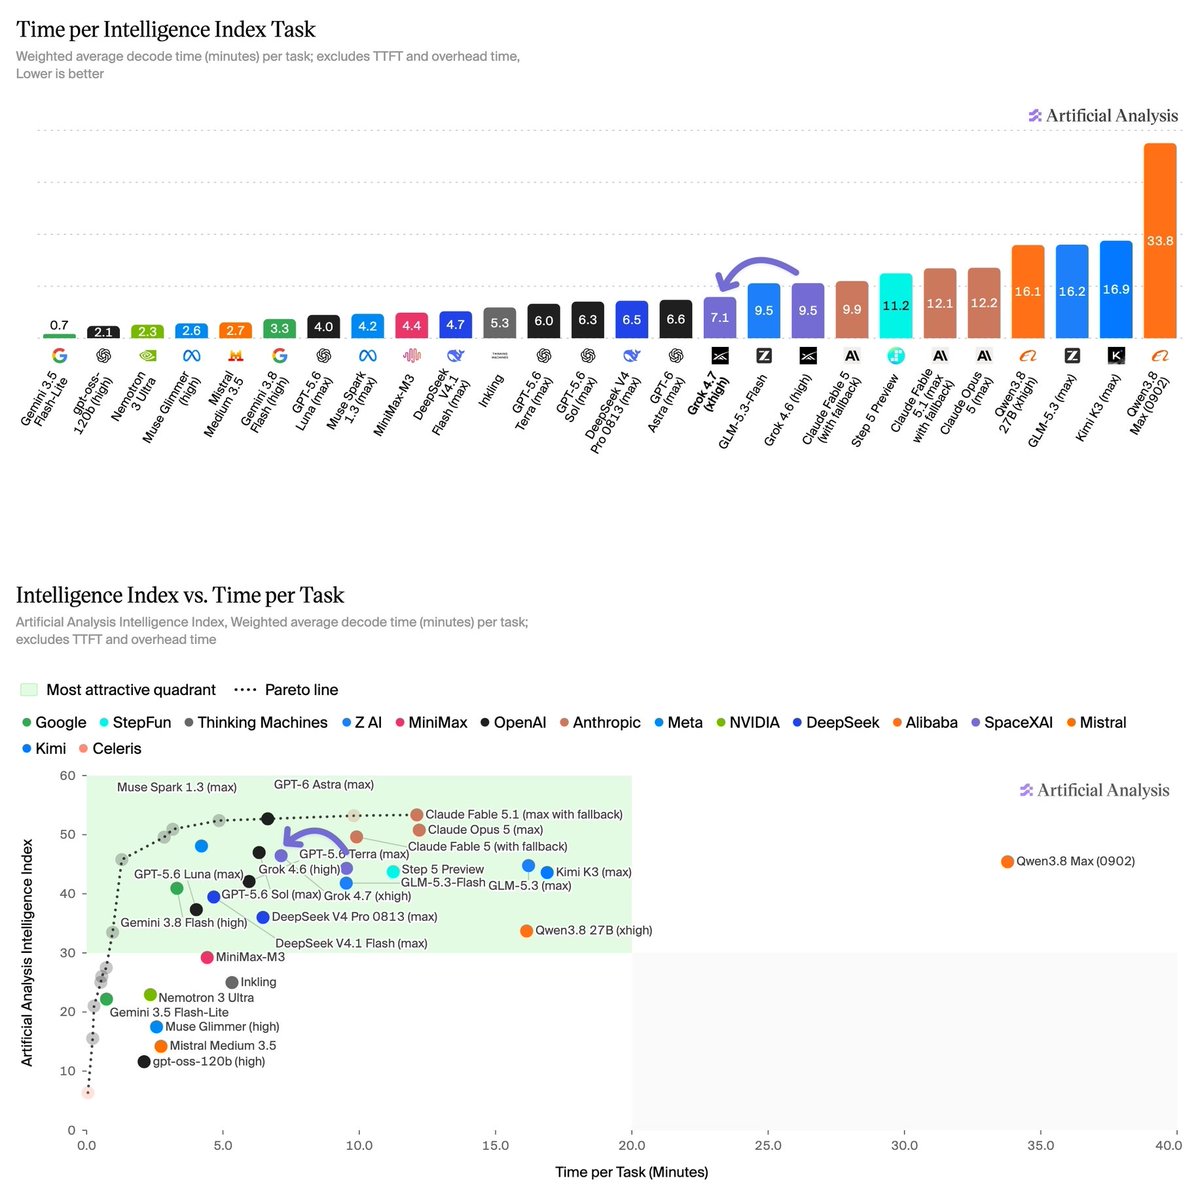
According to Choi citing Artificial Analysis, Grok 4.7 scored 46 points, a 2-point increase over version 4.6. It remains behind leaders like GPT-6 Astra and Fable 5.1, which scored 53 points.
Token Usage and Speed
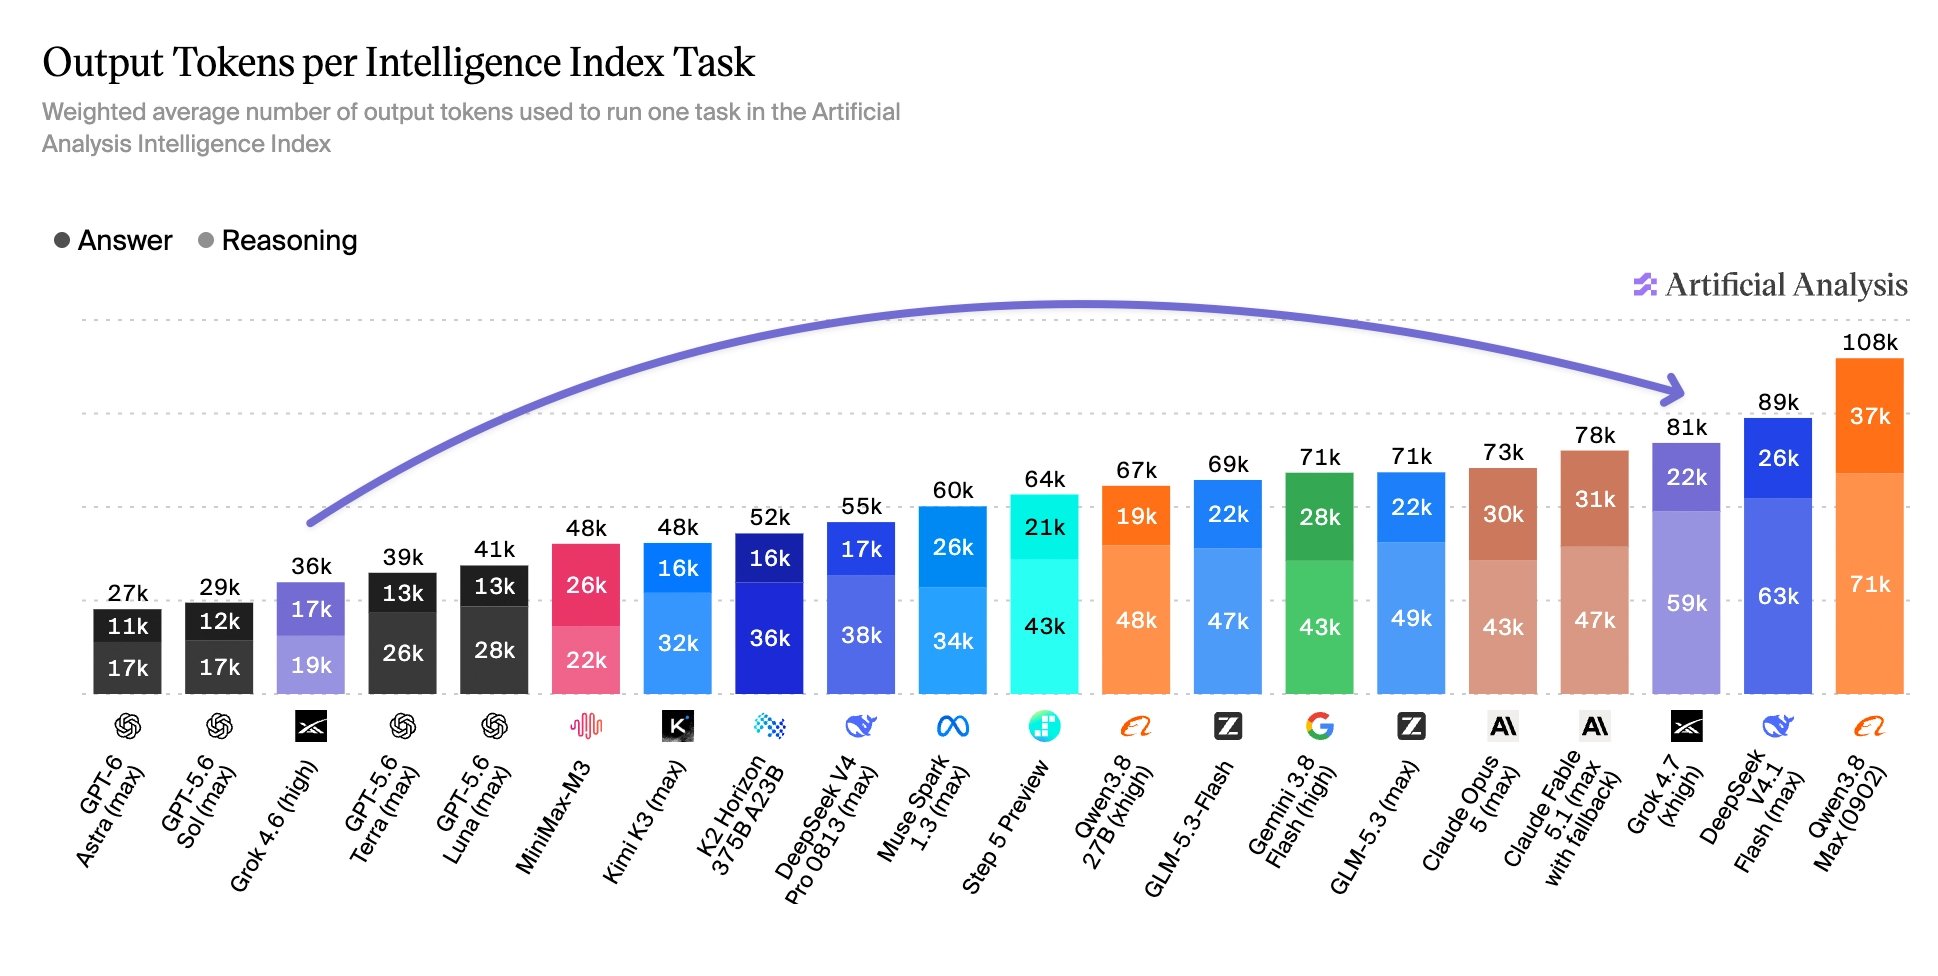
Output tokens per task increased by 125% to 81,000, significantly higher than competitors. However, generation time improved, dropping from 9.5 minutes to 7.1 minutes.
Knowledge Task Improvements
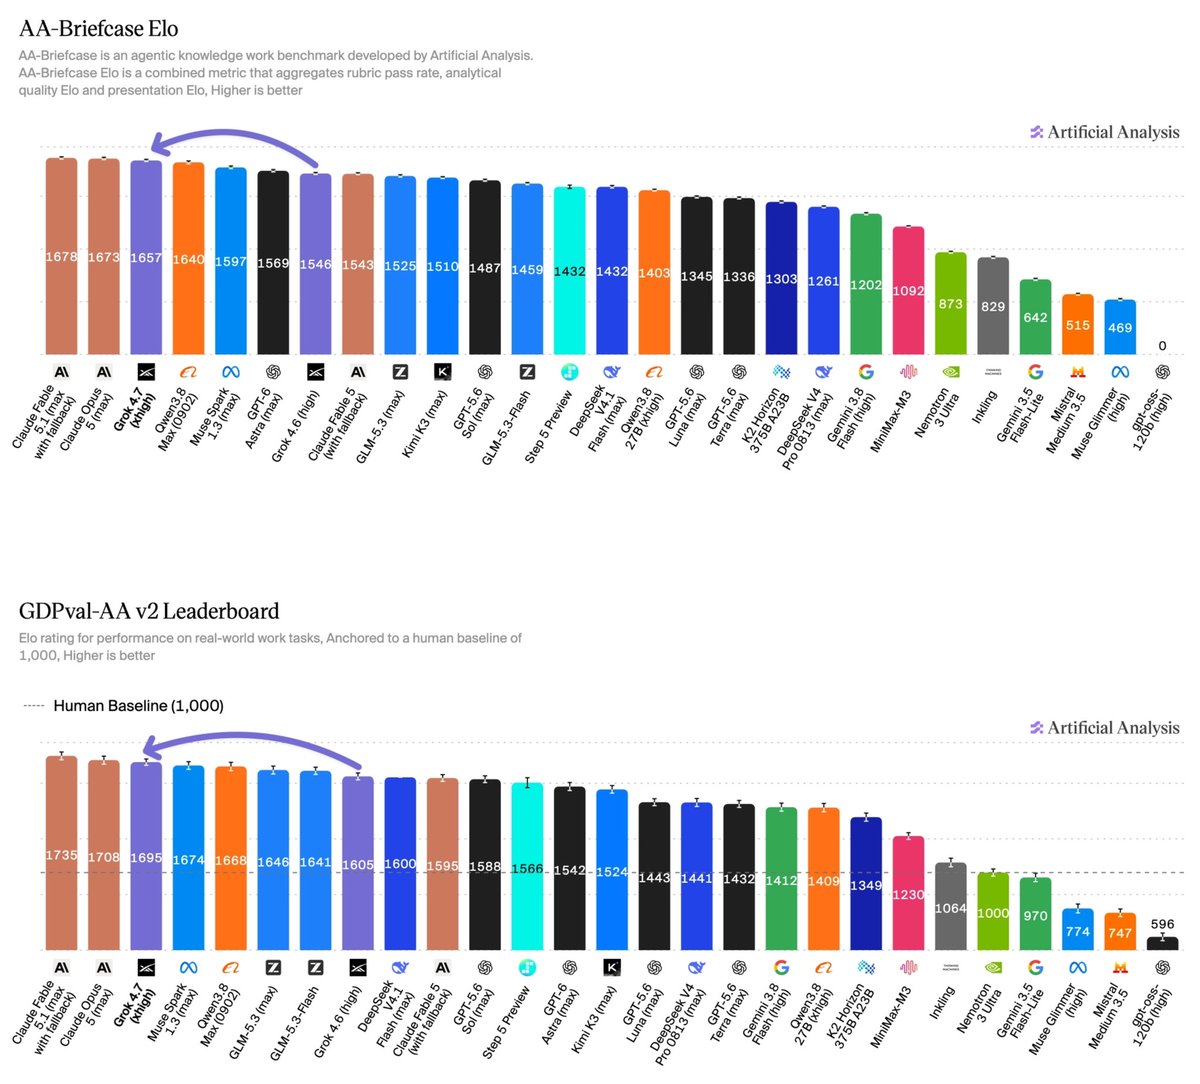
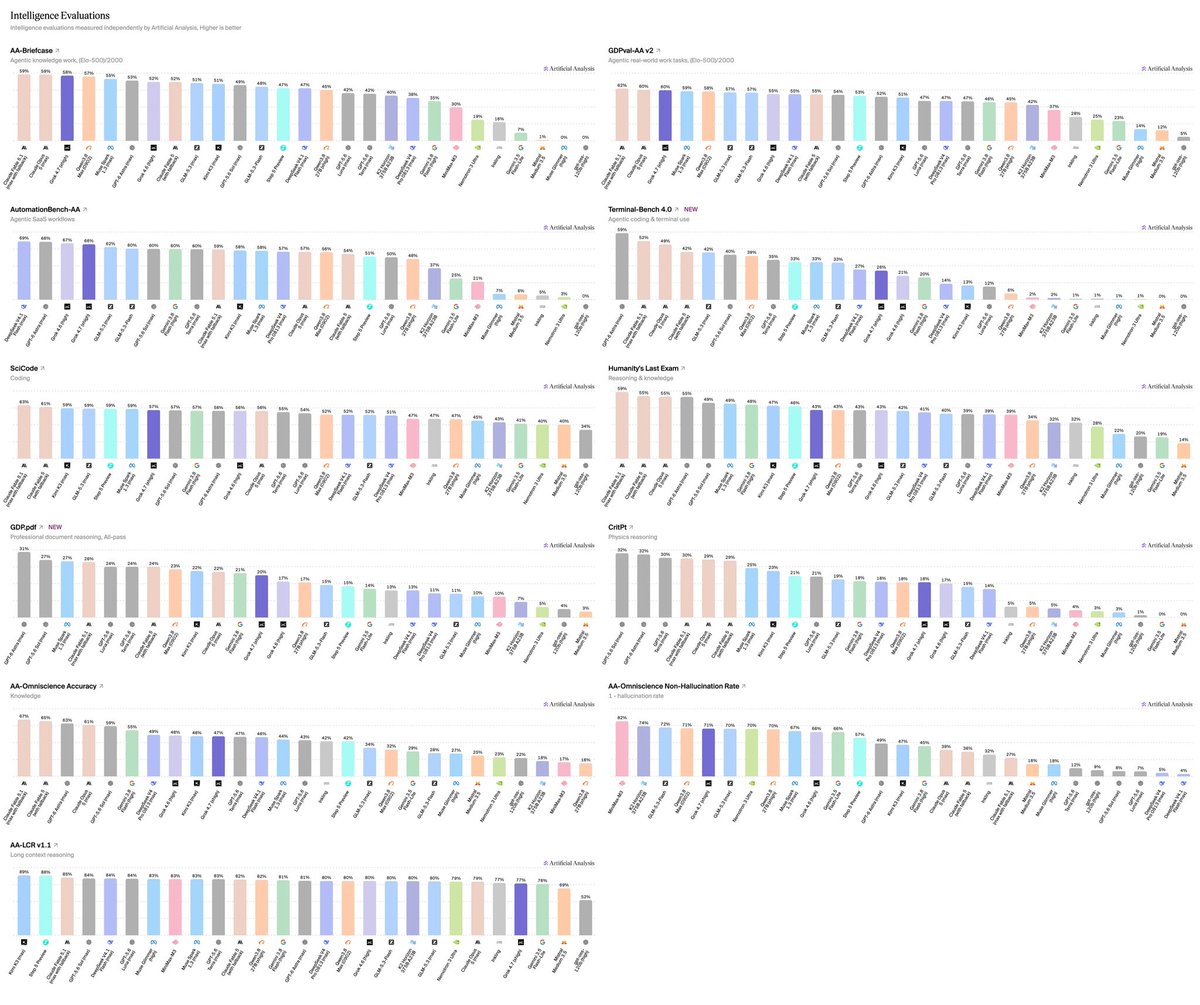
Grok 4.7 showed strong gains in the AA-Briefcase benchmark, particularly in analysis quality. However, performance in output presentation quality saw a slight decline.
Coding Agent Gains
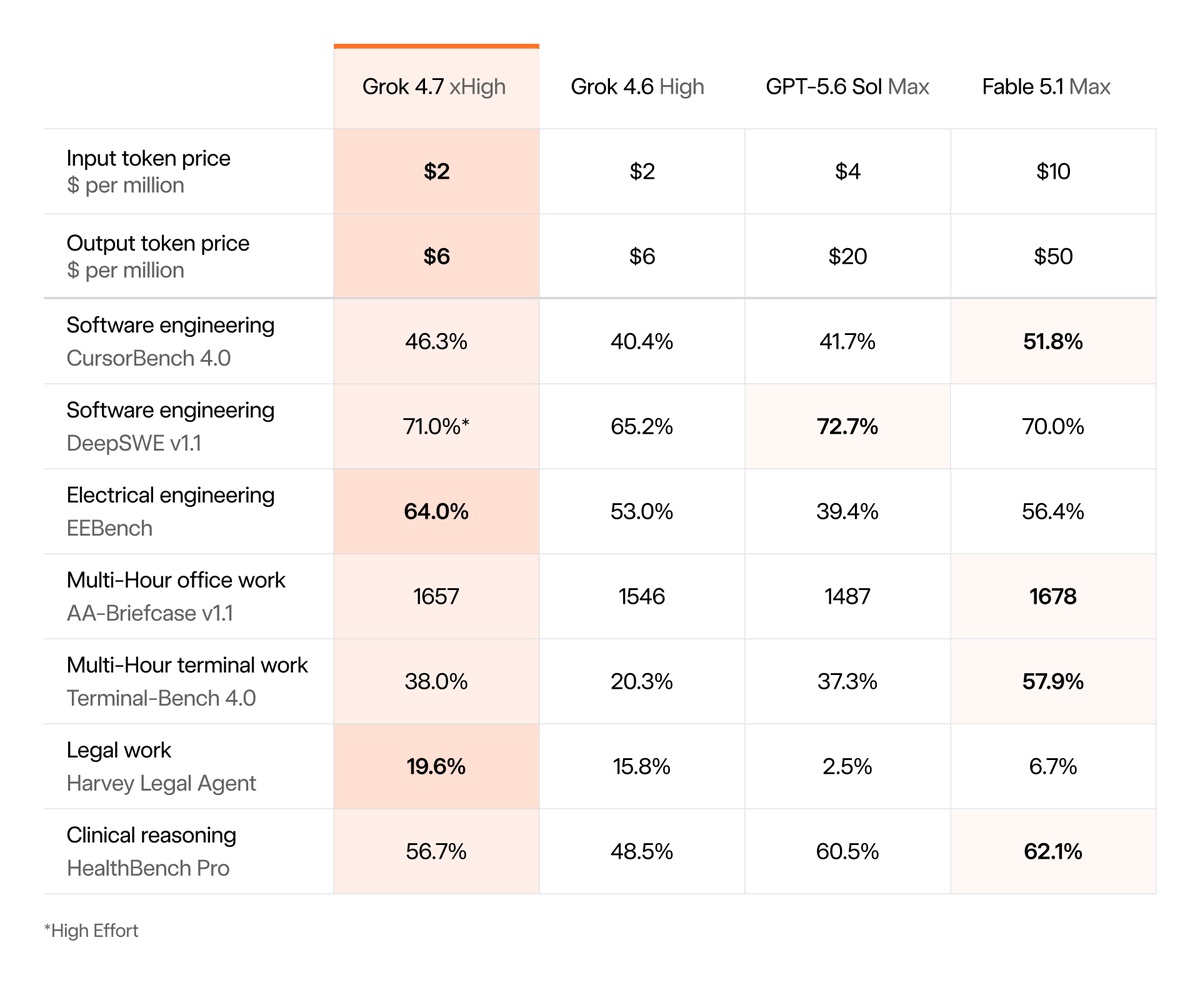
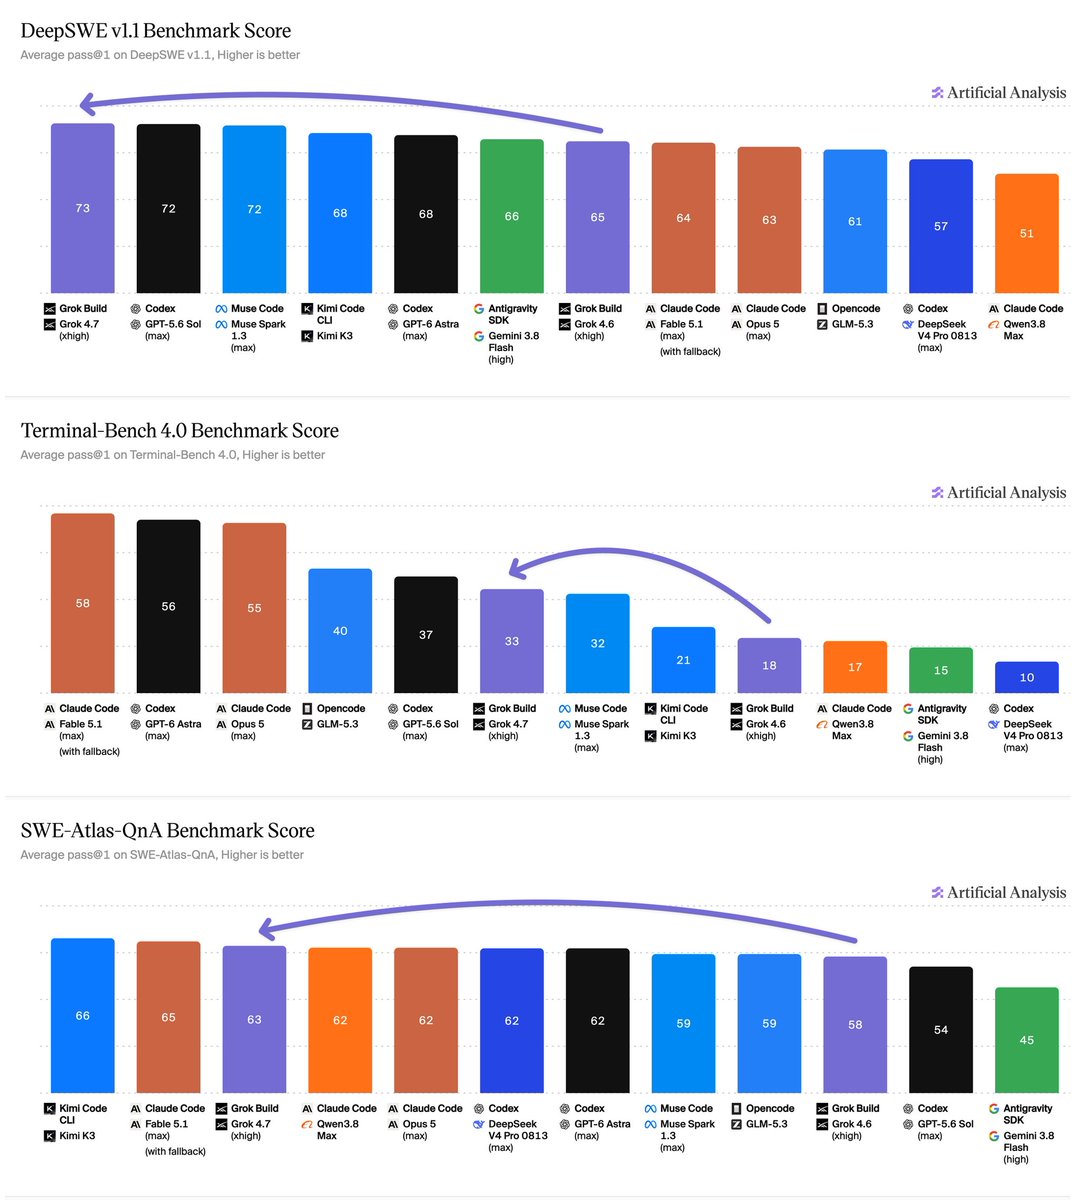
Coding agent performance rose from 47 to 56 points, surpassing GPT-5.6 Sol. Notable improvements were seen across DeepSWE and Terminal-Bench metrics.
Mixed Results in Other Areas
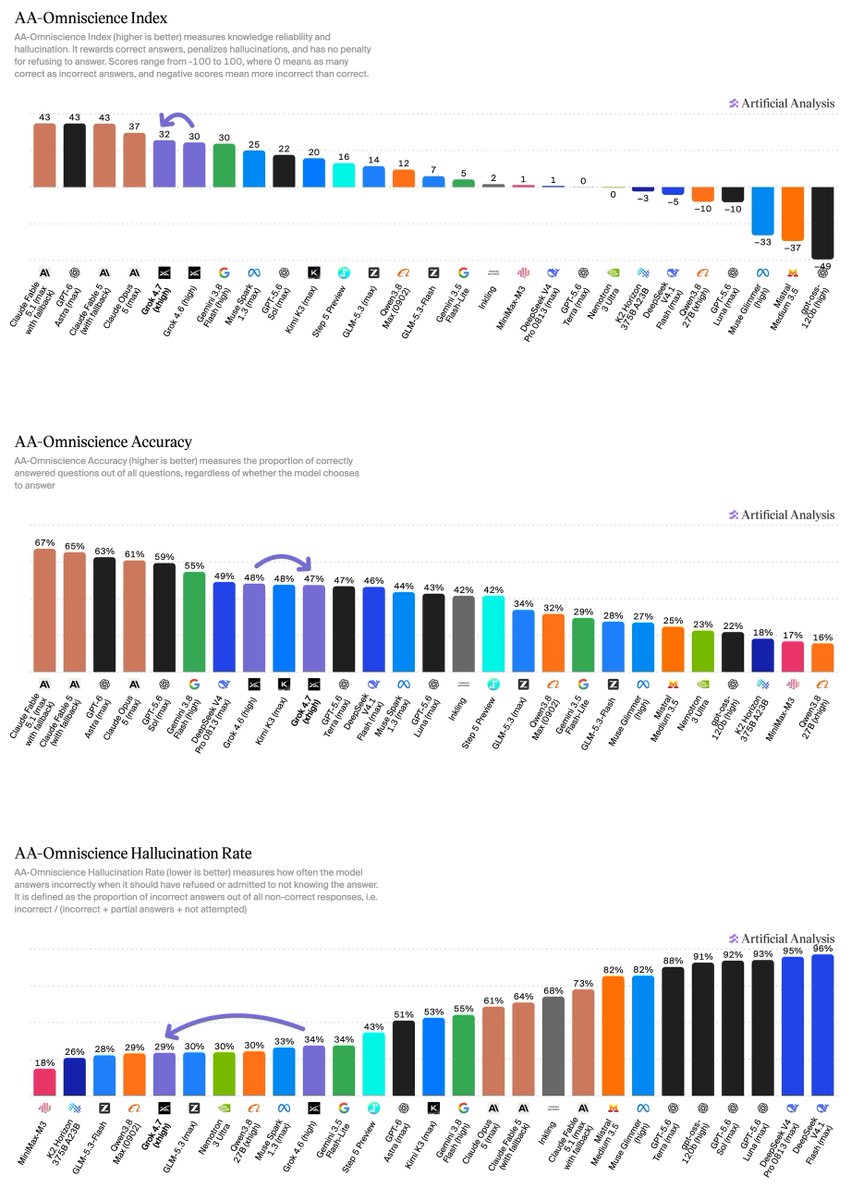
Performance in long-context reasoning and automation benchmarks remained stagnant or declined slightly. Hallucination rates decreased, though overall accuracy remained largely unchanged.
Competitive API Pricing
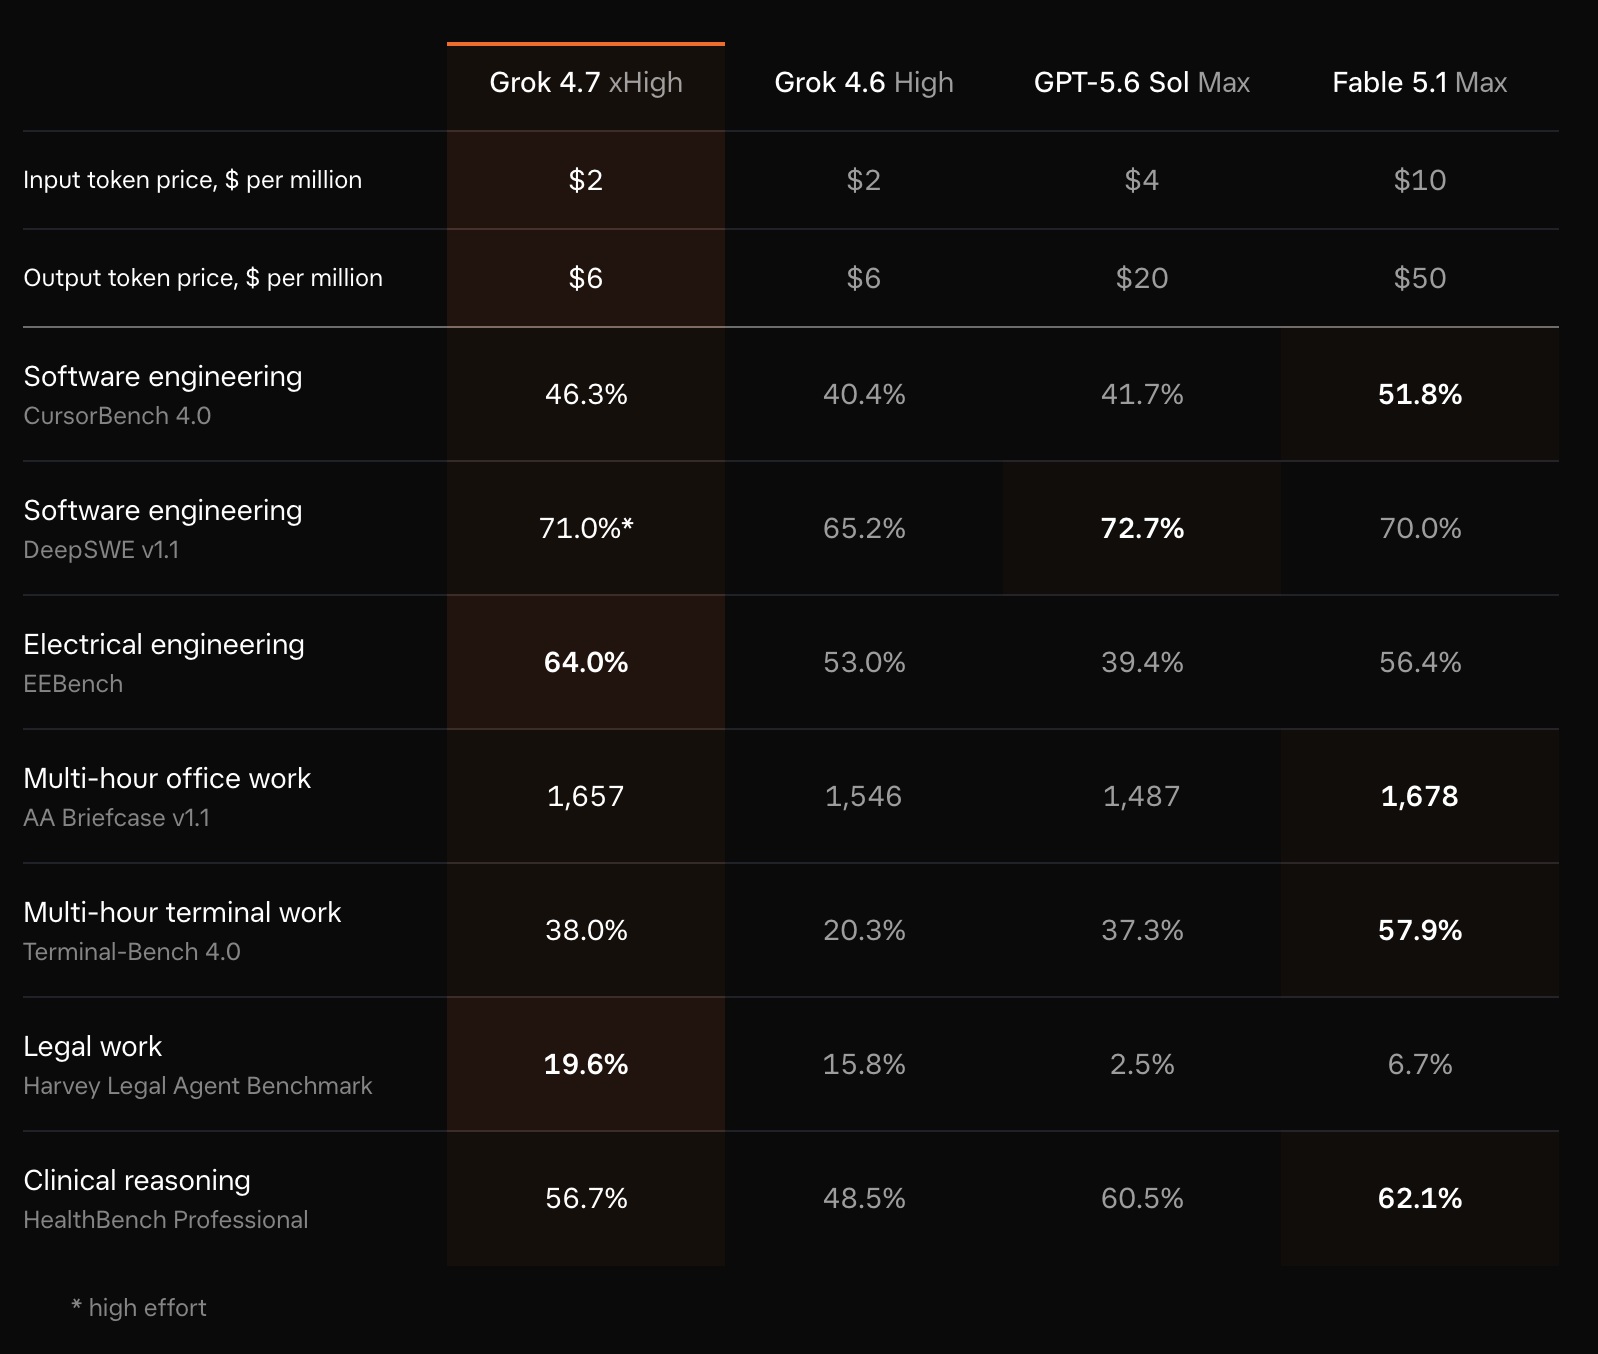
Grok 4.7 maintains the pricing of its predecessor, offering a cost-effective alternative to GPT-5.6 Sol and Opus 5. It supports a 500k token context window.
Cost-Efficiency Analysis
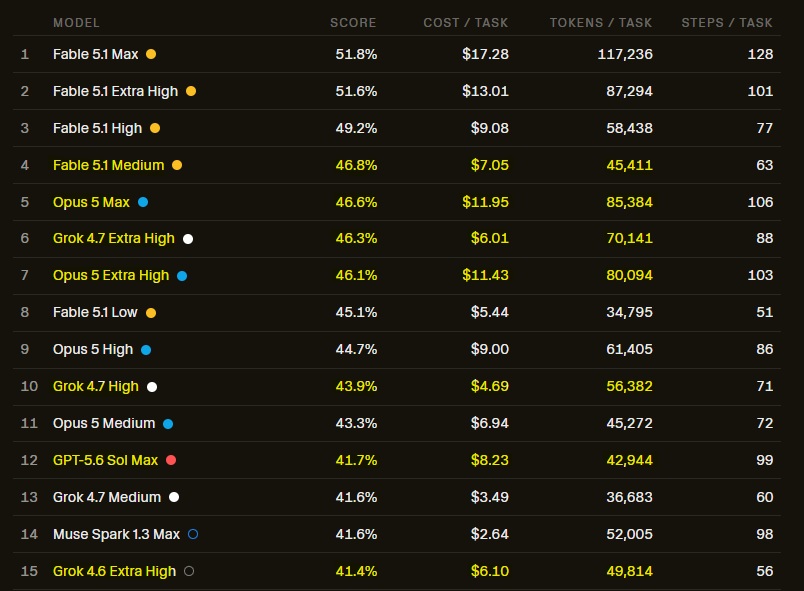
CursorBench data suggests Grok 4.7 offers better cost-efficiency than Fable 5.1 and GPT-5.6 Sol in mid-range performance tasks. However, Fable 5.1 still leads in peak performance settings.
Overall Assessment
While Grok 4.7 provides valuable improvements in coding and cost-efficiency, its overall intelligence gains are limited. It is not yet a definitive rival to the absolute top-tier models.
Source Information
Official release details are available at the x.ai news portal.
Source notes
This is a linked resource, not an independent verification of performance, cost or results. Check the original for current details.
- Collected
- 2026-09-21
- Discovered via
- www.threads.com
Top 10
Paid placement
- 01Wallpets 88 clicks$125
- 02Walltank 107 clicks$85
- 03Chowder 57 clicks$50
- 04Falconer 49 clicks$45
- 05Lemonpod 87 clicks$40
- 06Menta 33 clicks$35
- 07Sway 30 clicks$30
- 08Peon-Ping 27 clicks$25
- 09Zeron 89 clicks$20
- 10Guideless 22 clicks$15