提交資源


 한국어
 日本語
 Español
 Français
 Deutsch
 简体中文

 Português
 Bahasa Indonesia
 ไทย
 Italiano
 Tiếng Việt
 Türkçe
 Polski
 Русский

 SOURCE: X
 Gregor Zunic@gregpr07
瀏覽器使用 + Jev
Gregor Zunic 的動態 DOM 操作空間飛行搜尋示範。
 查看專案
Source linked · creator-reported demoView on X
A FIELD GUIDE TO JEV / VOL. 01
匯集 Jev 的真實專案、實用指南和來自全網的創意。
114 項資源 / 資源集
重設篩選AI-assisted summaries and translations. Check original sources for context and performance claims.
PadFlow(土地開發SaaS)的類型決策基準測試:模式、匿名標記資料行及用於信心校準模型的執行器。
 English
A chatbot built on a model that cannot generate text (TypeSafe AI's Jev, driven autoregressively).
EnglishCLI for TypeSafe AI's Jev evaluation model — typed questions in, structured JSON answers out.
EnglishOpen-source BYOK arena for Jev and other AI judges. Find failures, compare quality, cost, and latency.
EnglishA research project featuring an English–Icelandic dictionary that uses Jev to rerank results for better accuracy.
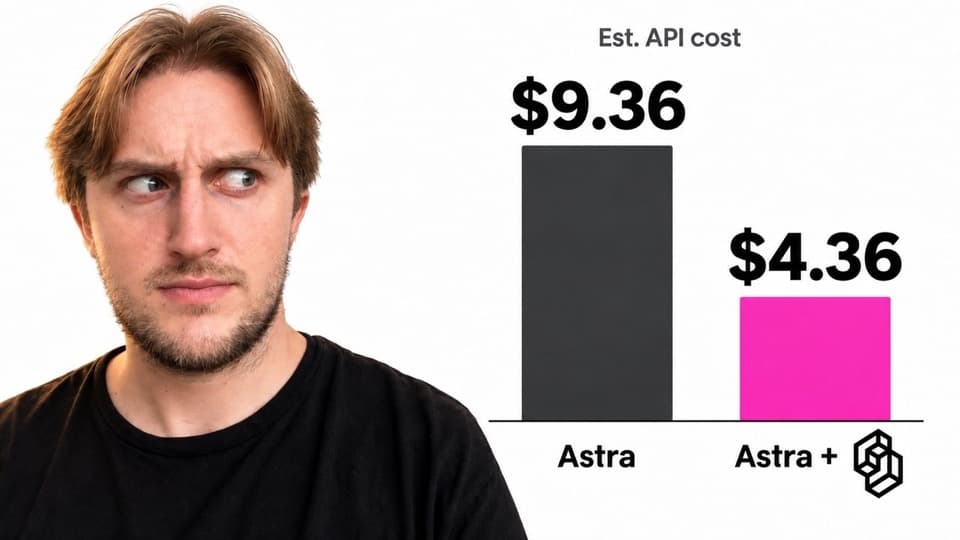
EnglishA YouTube guide discussing Jev's functionality, pricing, and performance comparisons with Astra, including benchmarking and parallel decision analysis.
EnglishA Jev-inspired decision interface for existing LLMs. Explicit choices, scores, calibration, and review thresholds.
EnglishA research project on GitHub conducting nine experiments and 28 predictions with fixed parameters, focusing on Jev's performance metrics.
EnglishPapers, open reproductions and independent evaluations behind System One models and Jev.
EnglishEvidence-backed index of real-world Jev (TypeSafe AI System One) use cases: repos, patterns, benchmarks, and measured results.
English发明 RLHF 的人,这次做了个不会说话的模型:Jev 独立研究报告。52 页 PDF + 50 条中文实测复现包 + 143 条可回溯数据表.
EnglishCurated catalog of System One / Decision Models — contributions for modelsystem.one.
EnglishA word-level language model whose output layer is Jev: n-gram drafter, Noul chunk verification, bits-per-token eval.
EnglishA small reproducible MuJoCo pilot comparing Jev, Claude Haiku, and reactive rules for pick-and-place.
EnglishCatch breaking API behavior hidden in OpenAPI prose with deterministic checks and TypeSafe JEV System One semantic review.
EnglishA show-and-tell capability study for Jev, TypeSafe's System One decision model.
EnglishRust port of TypeSafe system-one-adapter (LLM-backed system_one evaluations).
EnglishTypeScript experiments, evaluations, and latency benchmarks for TypeSafe's Jev model.
English@ai-sdk/typesafe-ai plus experimental_evaluate; use jev-latest as an evaluation model.
EnglishTyped JSON inference with DiffusionGemma, with Every and Jev benchmark results.
EnglishOffline Obsidian search with optional Jev reranking of results, requiring user approval before reranking.
EnglishDecision harness for TypeSafe Jev — confidence gates, shadow mode, recipes, and evals. Claude CLI 48.9s → Jev 1.3s on the same row-filter job.
EnglishJev (TypeSafe) vs. Gemini 3.8 Flash vs. GPT-5.6 Luna na anotação estruturada de sentenças do TJSP: qualidade, tempo e custo.
EnglishThis is a LLM Gateway that mimics typesafe ai structured output. Like an imposter Jev.
English Source linked · creator-reported demo
 贊助
 譯文摘要
 研究與資料