
 提交資源


 English
 한국어
 日本語
 Español
 Français
 Deutsch
 简体中文

 Português
 Bahasa Indonesia
 ไทย
 Italiano
 Tiếng Việt
 Türkçe
 Polski
 Русский
 返回實驗室
 JEVLAB NEWS Research & data
Anthropic 發布 Claude Opus 5.5
AI-assisted summaries and translations. Check original sources for context and performance claims.
Anthropic 推出了 Claude Opus 5.5,該模型在多數任務中表現優於 Fable 5.1,且成本降低了 40%。新版本優化了推理效率與寫作風格,並加強了安全評估機制。
翻譯摘要 · AI-assisted; check the original.
 翻譯摘要 · AI-assisted; check the original.

一覽完整討論串
使用AI獨立概述CHOI的連續貼文。圖片和影片歸原作者所有,原文中的主張未經獨立驗證。
模型發布概況
Anthropic 發布了 Claude Opus 5.5,其性能對標 Fable 5.1,但價格僅為後者的 40%。
定價與規格
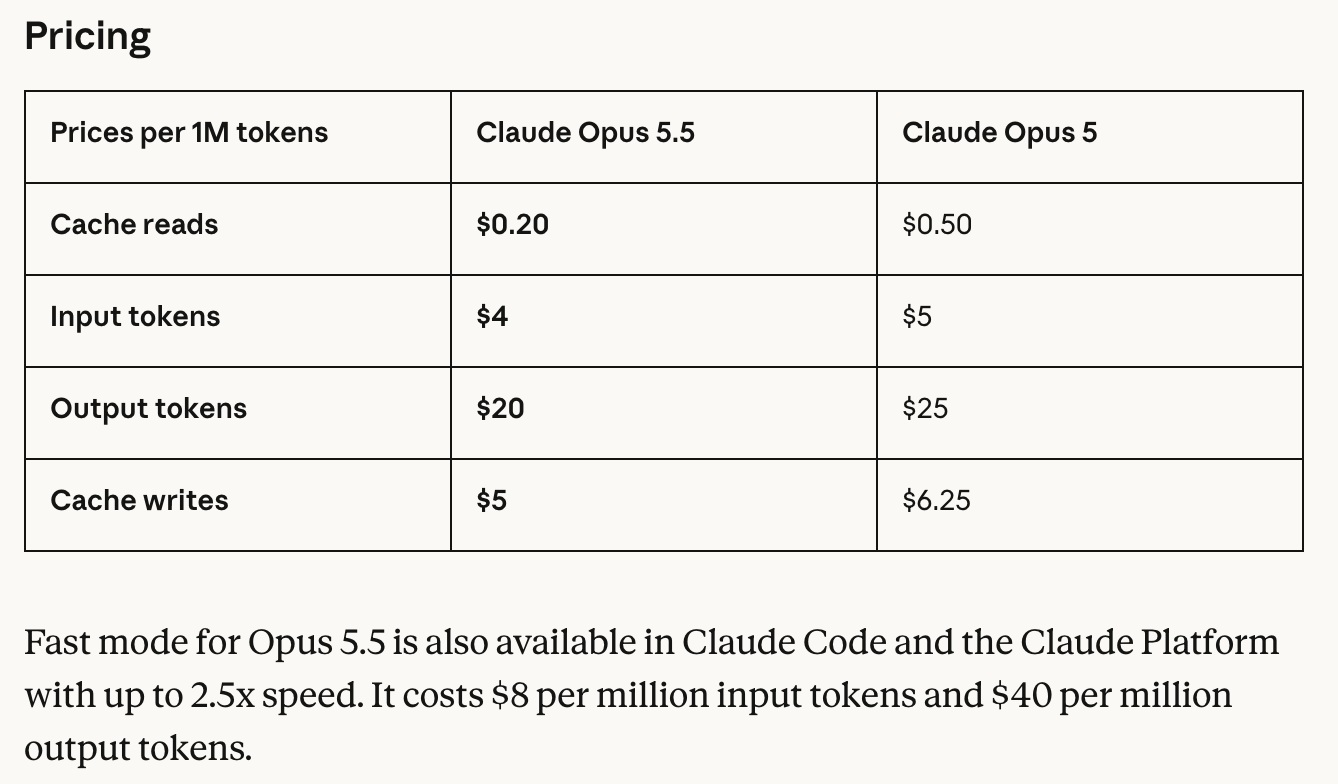
Opus 5.5 是 5.5 系列的首款模型,輸入價格為每百萬 token 4 美元,並提供五種推理強度選項。
基準測試表現
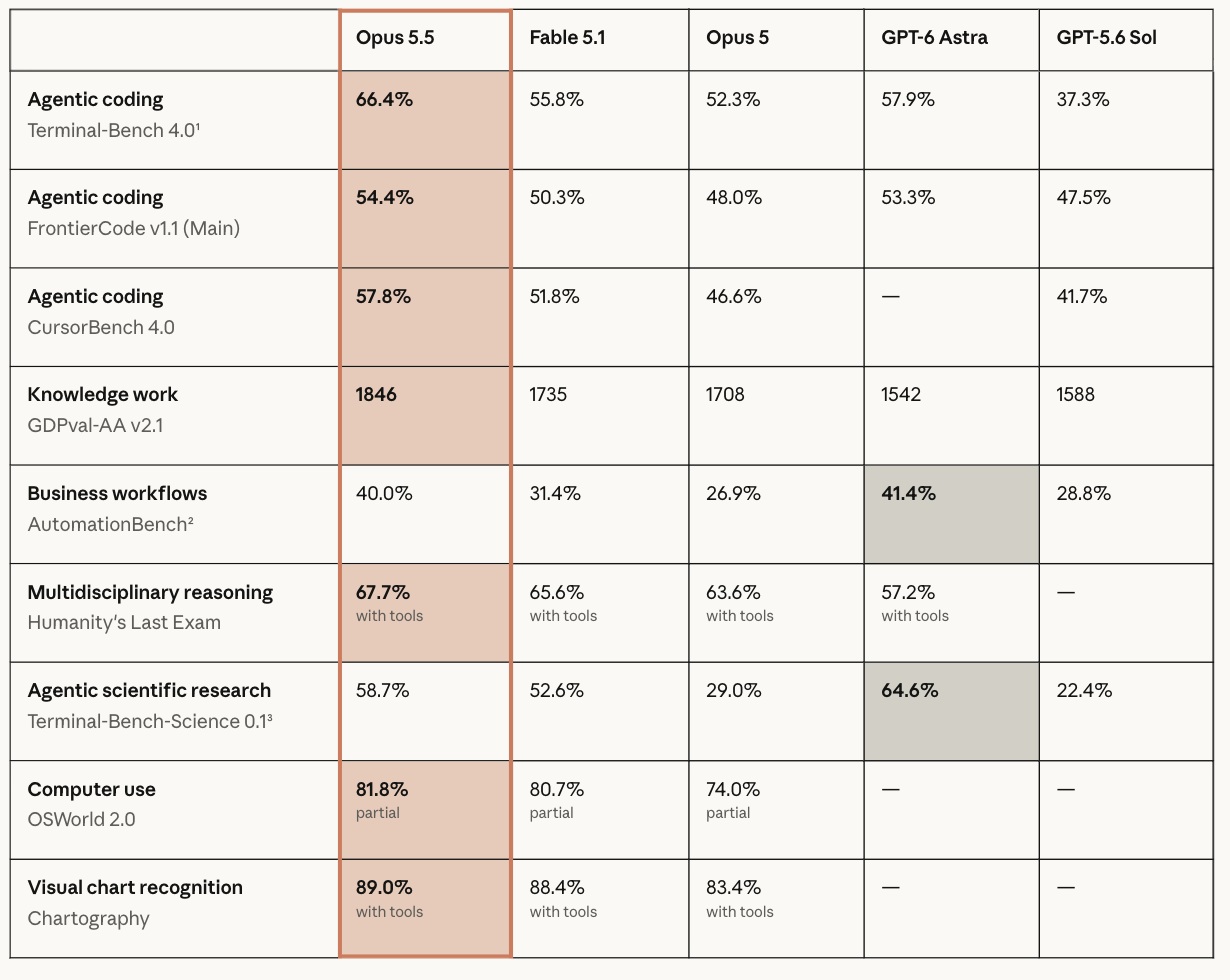
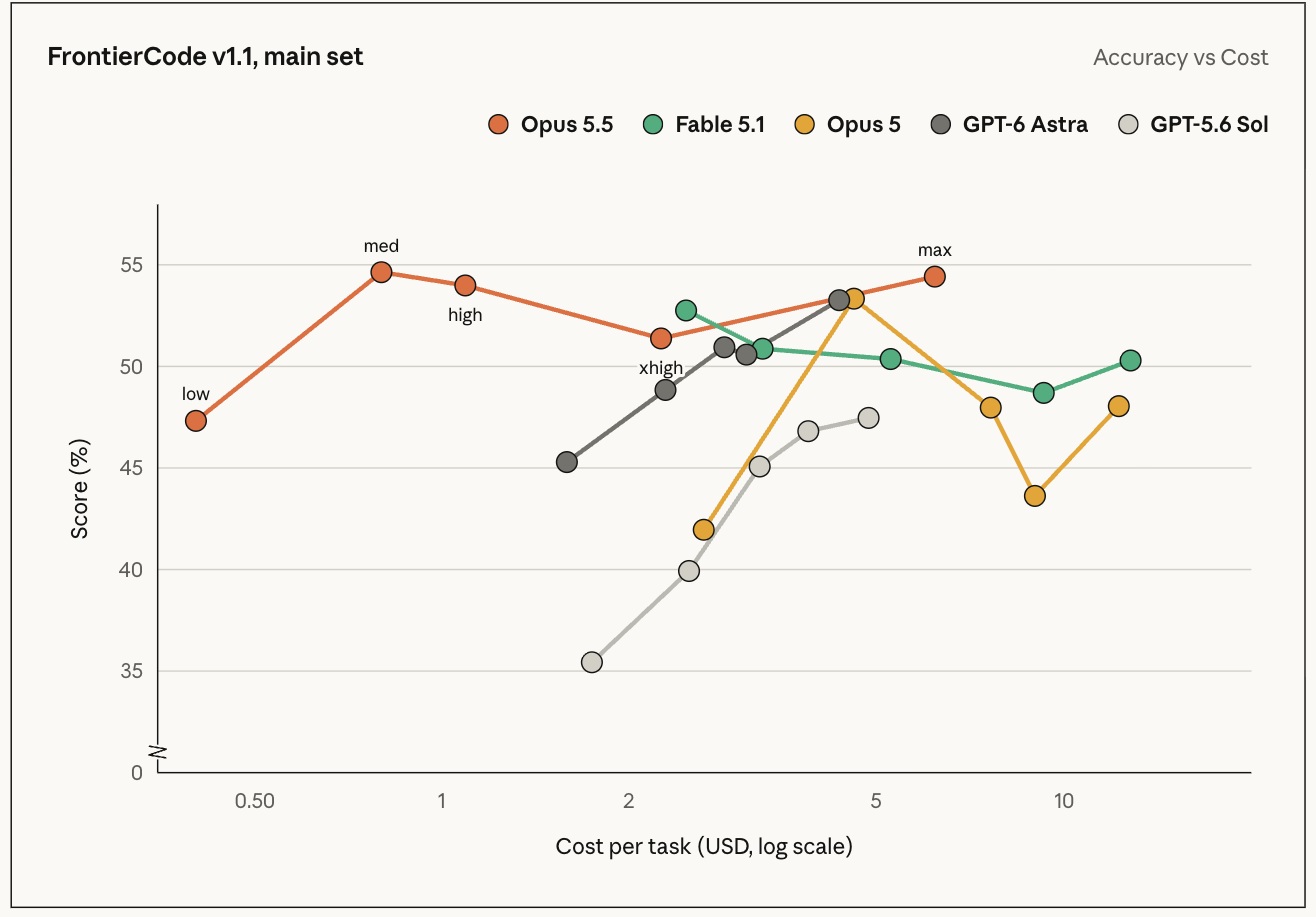
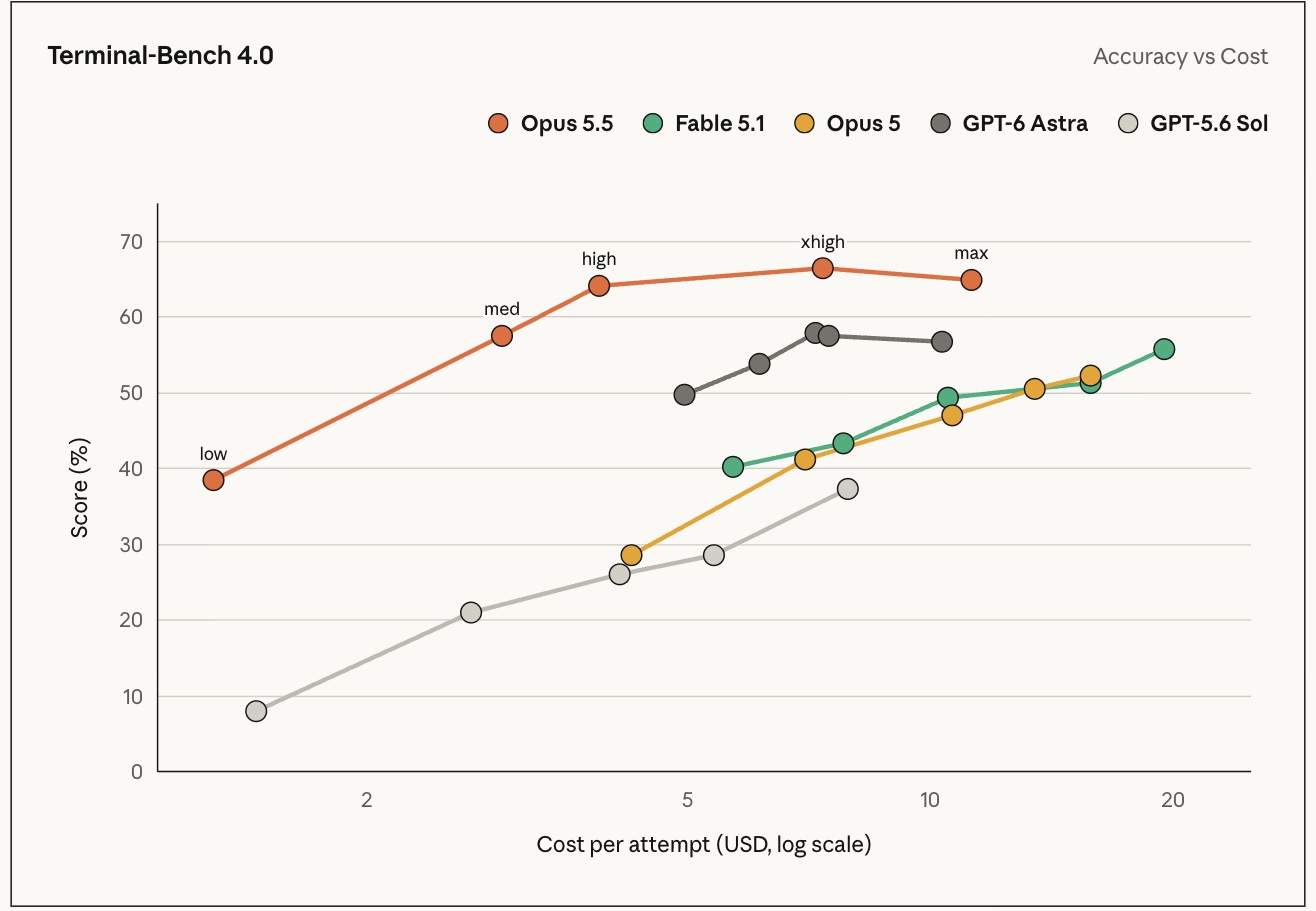
在 9 項評估中,Opus 5.5 在 7 項中獲得最高分,測試過程均在開啟安全防護的狀態下進行。
獨立機構評估
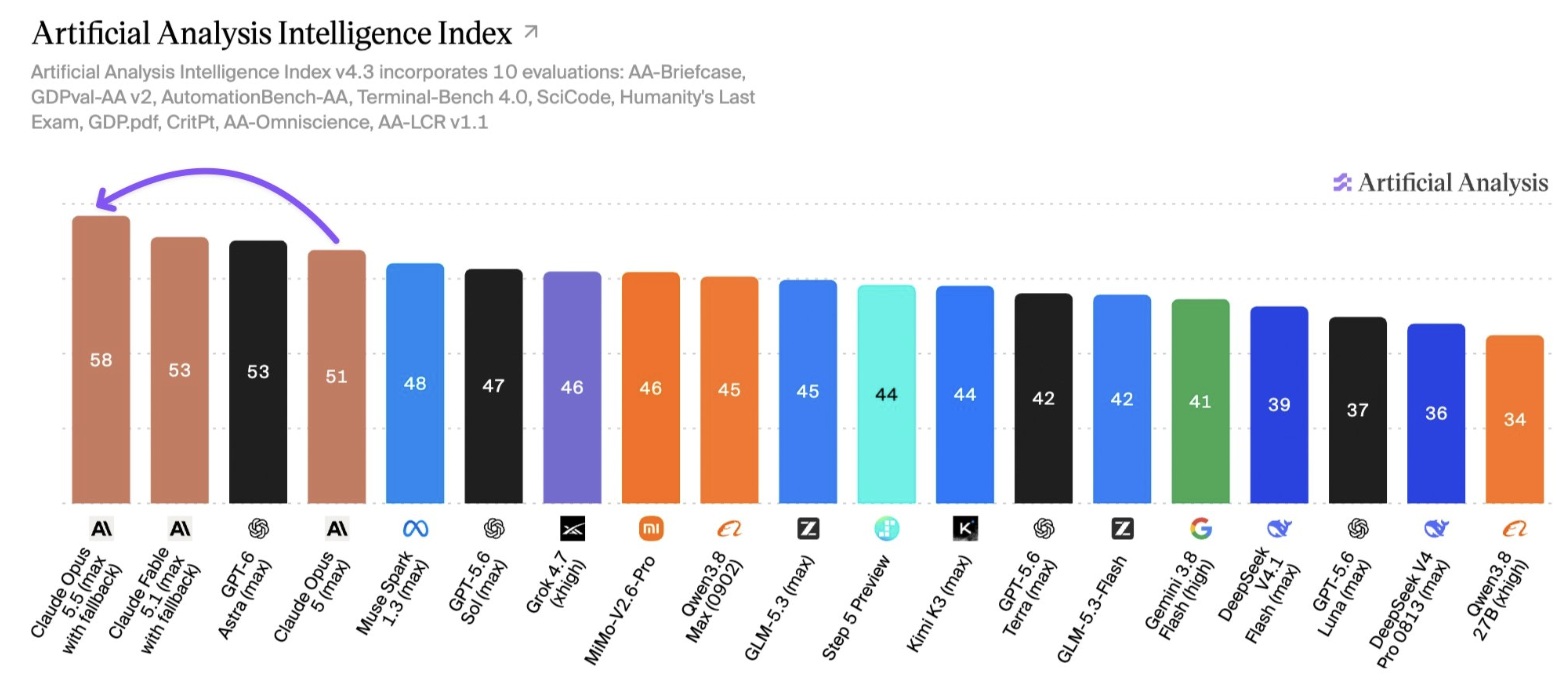
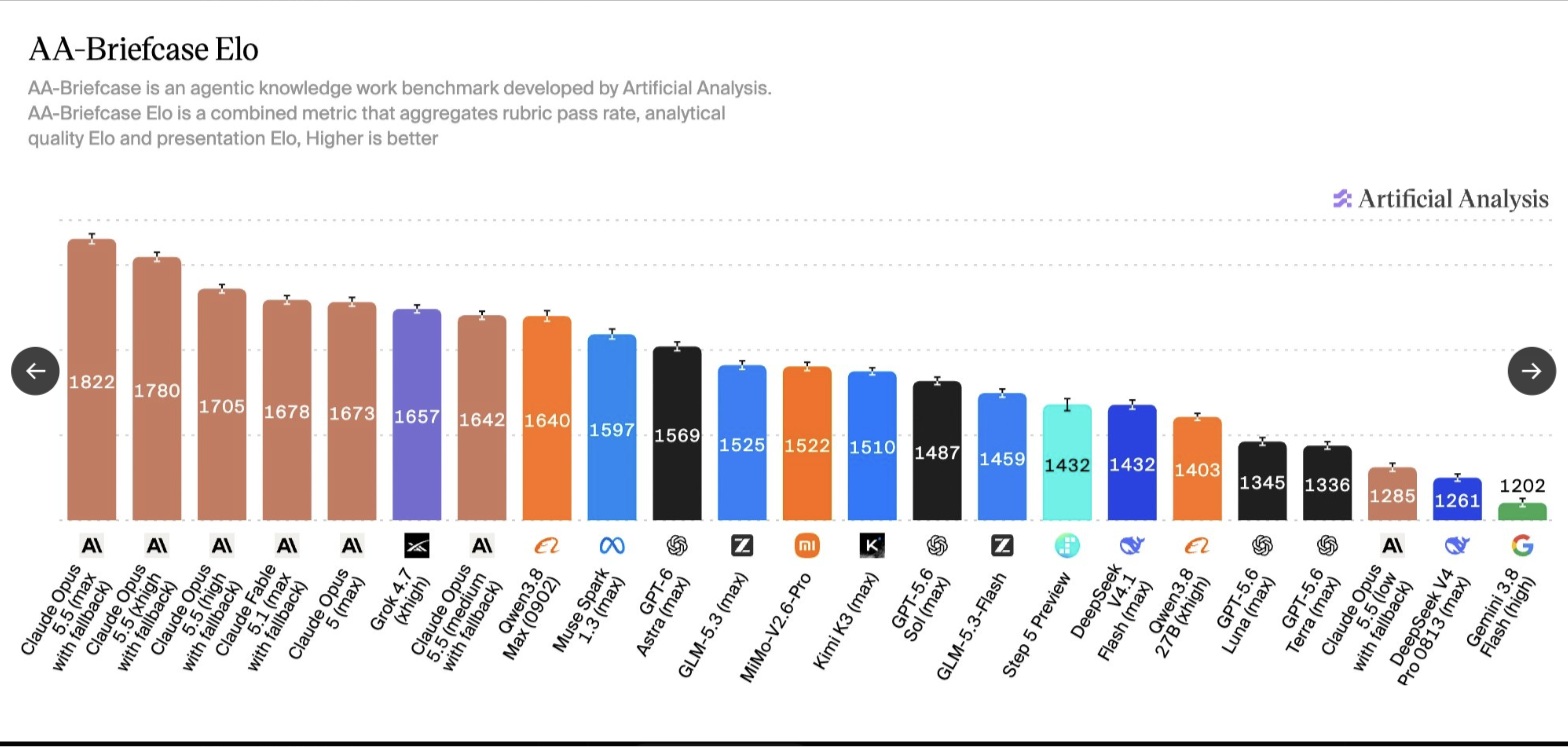
Artificial Analysis 的智力指數顯示,Opus 5.5 以 58 分位居榜首,領先於 Fable 5.1。
性價比分析
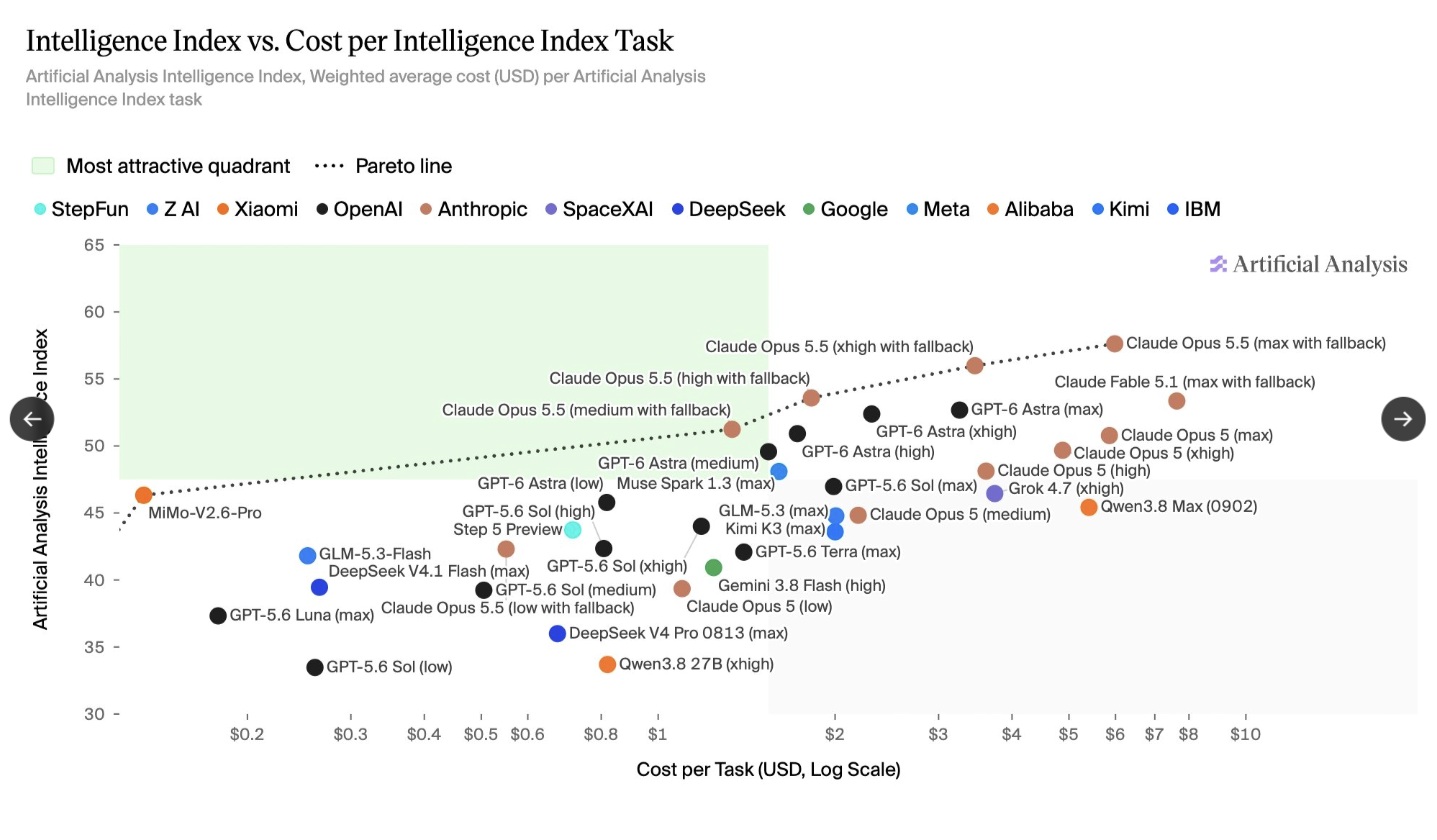
Anthropic 指出 'medium' 強度的性價比極高,在多項測試中以更低成本超越了競爭對手。
推理成本與效率
儘管 'max' 模式消耗更多 token,但其高得分表現確保了整體效率,並提升了用戶的使用額度。
實際應用案例
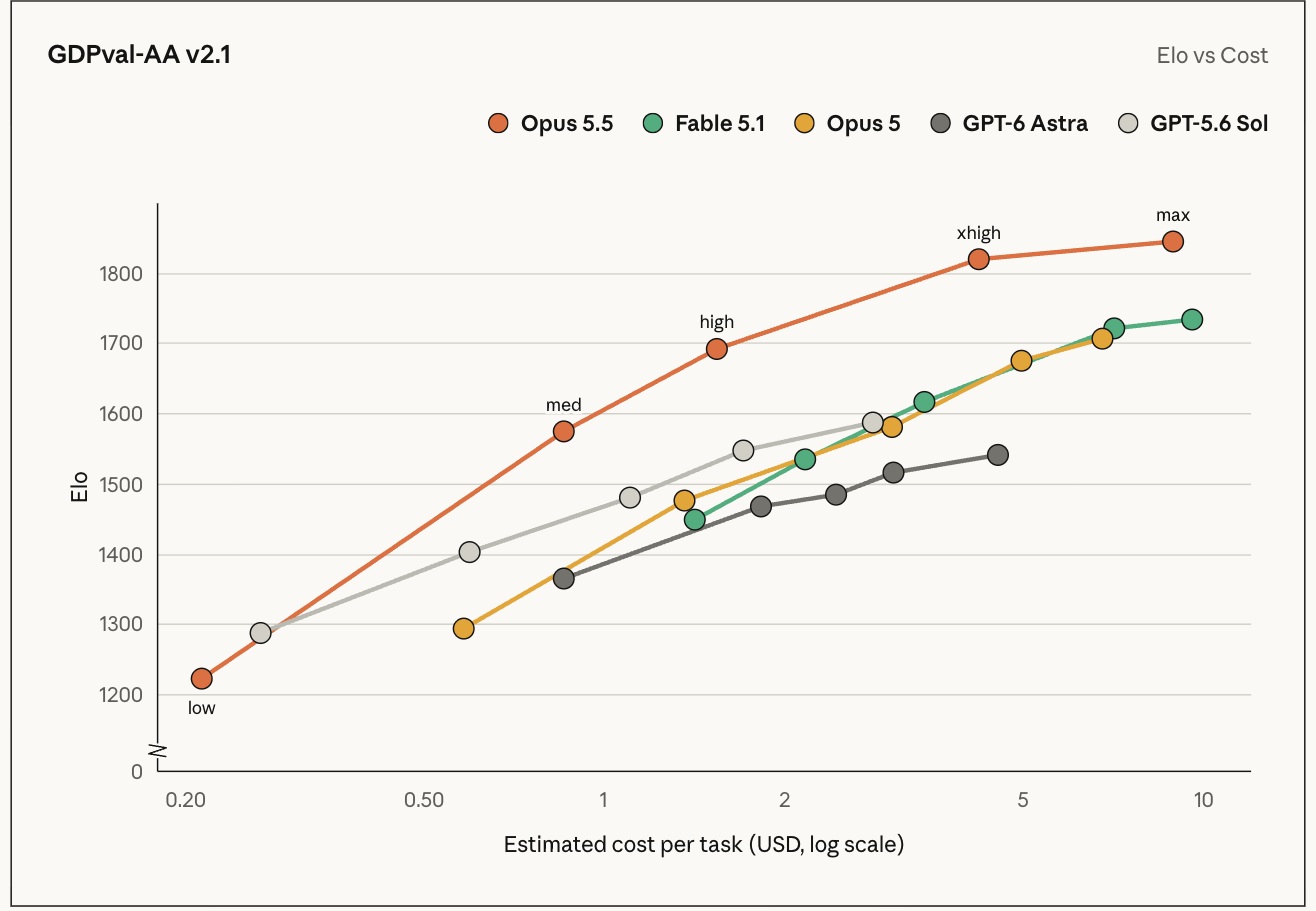
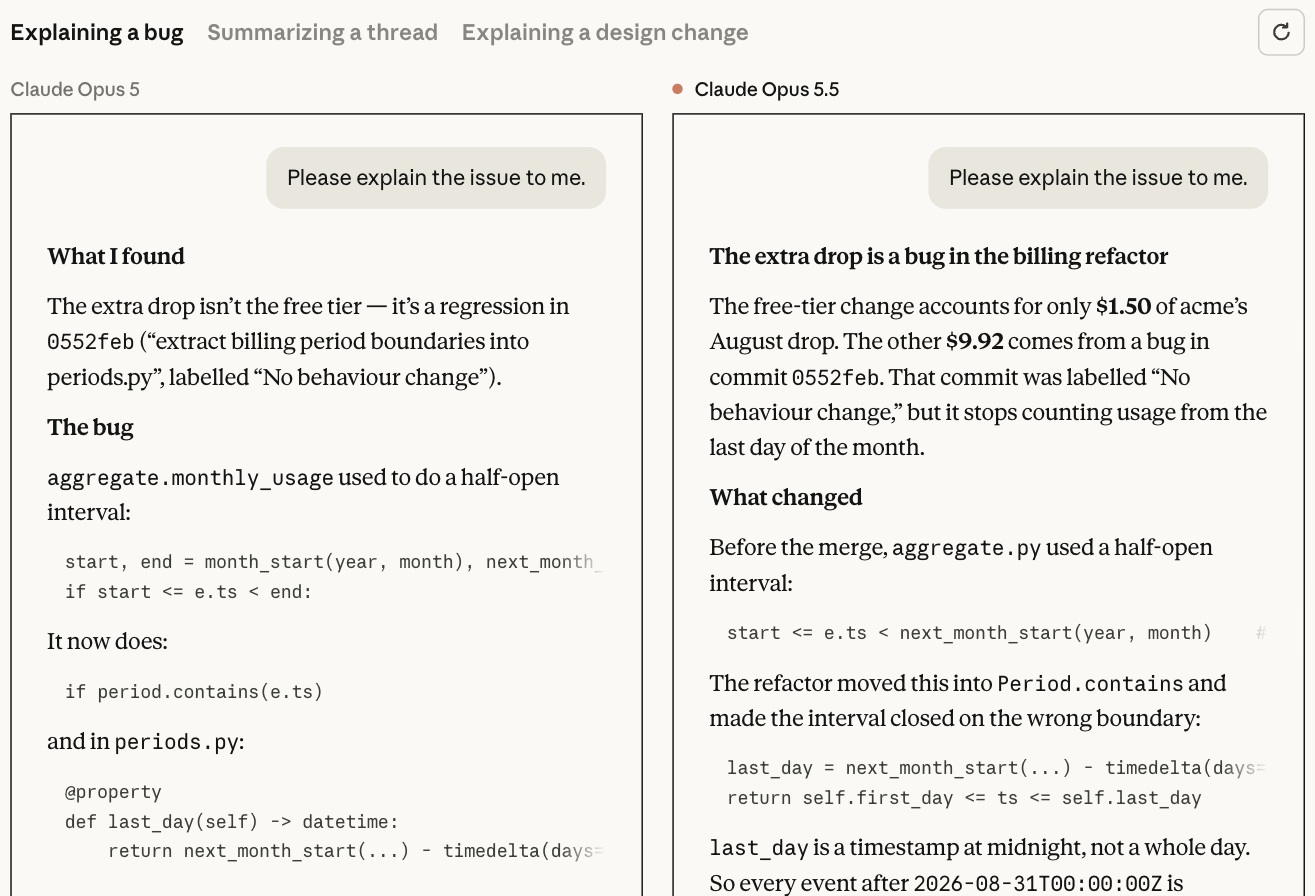
在代碼重構和審計任務中,Opus 5.5 的執行速度和準確性均顯著優於 Opus 5 和 Fable 5.1。
市場競爭格局
Opus 5.5 以更低價格提供更高性能,對 Fable 5.1 的定價策略構成了直接挑戰。
寫作能力優化
新模型減少了冗餘術語,能更準確地遵循寫作規則,從而縮短了用戶的審核時間。
安全與評估
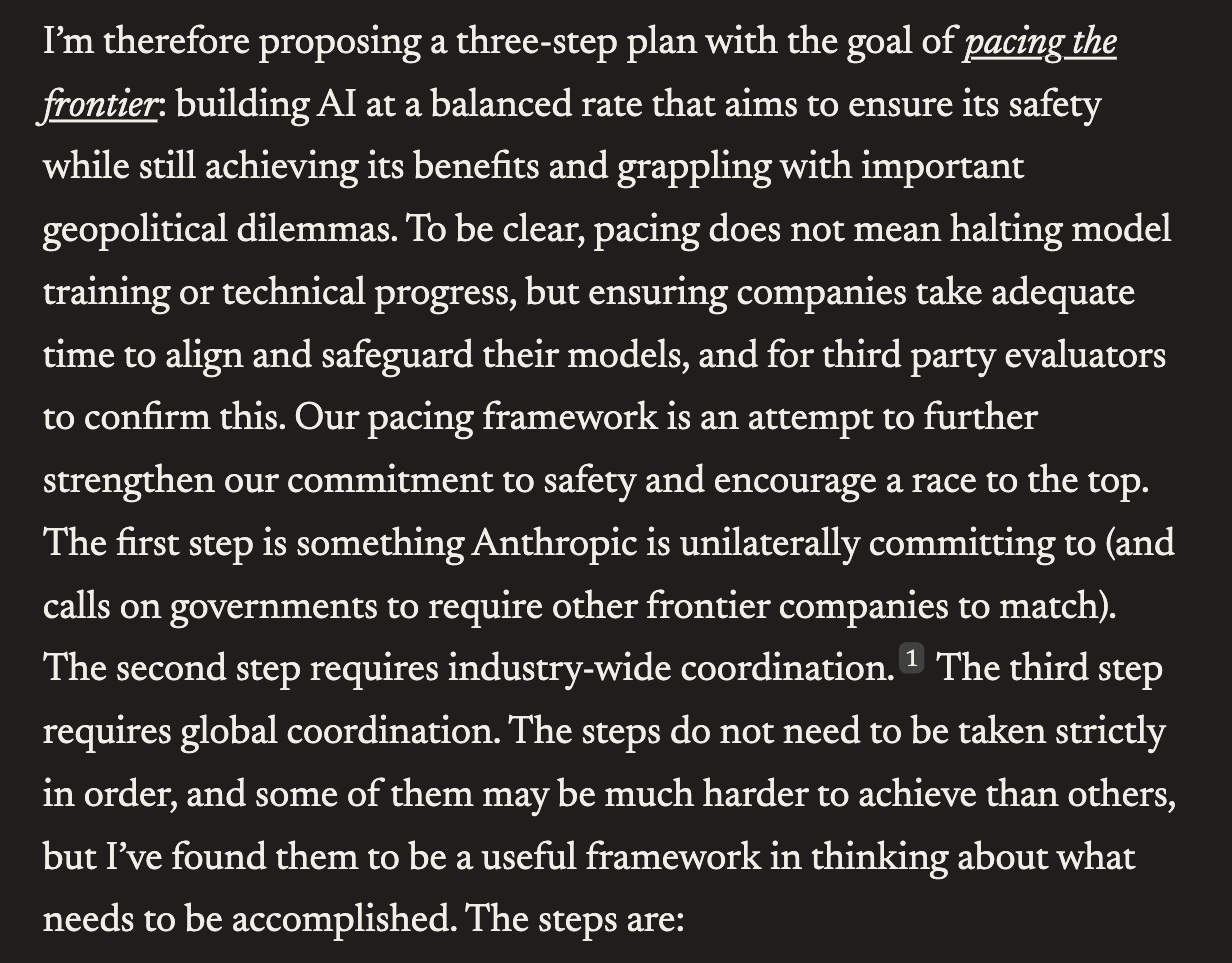
Anthropic 強調了外部評估的重要性,並致力於在模型開發中持續改進安全防護措施。
行業影響
激烈的價格競爭將推動 AI 代理服務的成本下降,使維持高昂的溢價模型變得更加困難。
官方信息
有關此次發布的詳細信息,請訪問 Anthropic 官方公告頁面。
Source notes
This is a linked resource, not an independent verification of performance, cost or results. Check the original for current details.
- Collected
- 2026-09-23
- Discovered via
- www.threads.com
前十名
Supporter
- Wallpets 119 點擊次數88d left
 W
- Walltank 122 點擊次數88d left
 W
- CChowder 73 點擊次數88d left
- Falconer 62 點擊次數88d left
 F
- Lemonpod 98 點擊次數88d left
L
- Menta 46 點擊次數88d left
 M
- Sway 41 點擊次數88d left
S
- Peon-Ping 37 點擊次數88d left
 P
- Zeron 98 點擊次數88d left
 Z
- Guideless 31 點擊次數88d left
 G